vllm-ascend
Reference: v0.27.1rc1, a release candidate. Its release notes specify upstream vLLM v0.27.1. This page considers full-attention request/KV paths; the selected scheduler depends on configuration.
Tagged behavior
ShortRequestFirstRequestQueue classifies requests into immediate, short and long queues. Immediate requests take precedence; sufficiently old long requests are promoted ahead of short requests. This is a class-and-aging policy, not simply sorting by length. Queue implementation
BatchJobAwareRequestQueue uses job-level decode-length predictions, available admission budget, cold-start requests and length buckets. A fixed per-request key cannot reproduce its shared history. Job-aware implementation
In the relevant preemption path, RecomputeScheduler.schedule asks the connector to offload. Success proceeds to normal preemption; failure finishes the local request through _finish_recomputed_request and returns stop_reason="recomputed". DyntraLBPolicyMixin also prefetches remote KV and waits in WAITING_FOR_REMOTE_KVS. Recovery, prefetch
Device inputs and padding
_pad_for_sequence_parallelism rounds scheduled tokens to a TP-size multiple
when the relevant SP path is enabled. _determine_batch_execution_and_padding
then selects a graph descriptor and checks uniform decode from per-request
scheduled lengths and computed state. With DP, metadata synchronization can
pad ranks to a common maximum and redispatch the graph mode. Explicit eager
execution returns a non-graph descriptor; graph eligibility is separate from
logical admission. These are conditional paths, not a universal NPU rule.
SP and graph selection,
DP coordination
The FIA TND input requires the final query-length boundary to equal the hidden-state token dimension. Padding can therefore insert a dummy request, not merely extend a flat tensor. The full-attention builder also pads sequence length and block-table metadata to that dummy row; dummy outputs are trimmed and KV writes use only actual tokens. Query boundaries, metadata consistency
A single-rank cost can round tokens without changing request progress.
Cross-rank graph agreement and per-request boundary validation require more
than aggregate cost terms. The current example does not model graph capture
or padded device buffers.
Executable serQ approximation
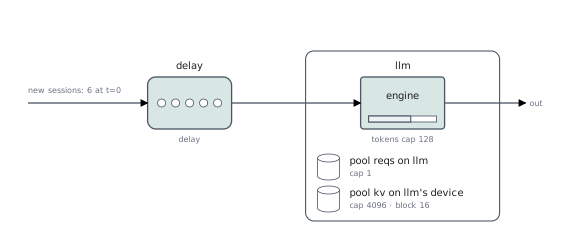
// FCFS lanes from vllm-ascend v0.27.1rc1: immediate, aged long, short, long.
// This full-attention example models local admission, not job prediction or remote KV.
let short_tokens = 128;
let max_wait = 0.003;
def waiting_class(urgent, prompt, elapsed) {
  urgent ? 0 : prompt > short_tokens && max_wait > 0 && elapsed >= max_wait ? 1 : prompt <= short_tokens ? 2 : 3
}

fn main() {
  workload {
    arrive batch(6);
    turn {
      set prompt = serial == 1 || serial == 5 ? 256 : 64;
      set immediate = serial == 4;
      set out = serial == 0 ? 4 : 1;
    }
  }
  device npu { kv cap 4096; }
  engine llm on npu {
    reqs cap 1;
    tokens cap 128;
    // One request: admitted with blocks for its whole sequence, so nothing
    // grows; `admitted` is the moment it is admitted.
    request (prompt, output) {
      mark admitted;
      prefill (prompt);
      decode (output);
    }
    schedule {
      advance running each at most (128);
      admit waiting while (running.preempted == 0) each at most (128)
        taking reqs (1), kv (prompt + output);
    }
    execute (0.001);
  }
  pool reqs on llm { queue by (waiting_class(immediate, prompt, waited)); }
  pool kv on npu { block 16; }
  stage delay : delay;
  server {
    run delay (cost(delay, serial == 2 ? 0.001 : serial == 3 ? 0.002 : serial >= 4 ? 0.003 : 0));
    llm (prompt, out);
    // which client was served, and when it was admitted
    observe selected = serial;
    observe admitted_at = llm.admitted;
  }
}
This example reevaluates immediate/aged-long/short/long precedence before each admission selection, using waited for elapsed queue time and FIFO ties. Its six requests are selected in order 0, 4, 1, 5, 2, 3; disabling aging with max_wait = 0 produces 0, 4, 2, 3, 1, 5. Request slots, KV capacity, token budget and chunk size are explicit; prompt and output capacity is allocated upfront to avoid recovery in this example.
Remaining gaps
| Requirement | Current mechanism | Remaining gap |
|---|---|---|
| Waiting-lane selection | Selection-time queue by and waited model FCFS class precedence and aging |
Priority-lane configuration and lane-specific prepend behavior |
| Job prediction and cold start | Session attributes | Shared job history and completion-driven predictor updates |
| Remote KV arrival | lease, load, release, explicit transfer |
Connector success/failure, cancellation and readiness protocol |
| Offload or remote recompute | preempt lifo, computed-aware local recovery |
Choose a recovery target and finish/forward to another engine |
Aging changes selection at an admission attempt; it does not schedule an independent wakeup timer. Shared job history and connector behavior remain outside this example.
The current IR can retain source memory through a transfer and preserve a local request's known progress on re-admission. Those mechanisms do not by themselves implement Ascend's connector or routing policy.
Validation
this reduced example links and completes its six requests. It has not been compared request by request with the Ascend scheduler or runtime.